Inside and around the platform
Three components on one shared context
Everything on the left ships with VaultSpeed and runs in your cloud. Everything on the right is yours already. The context store speaks MCP, so both sides work from the same data model, lineage and logic.
Inside VaultSpeed
 Git workspace
Skills, agents and every generated artifact, versioned
Your work is versioned and reviewable.
A persistent workspace in your Git: models, code, documents, analysis and lineage, every change tracked and reversible, built to be extended.
 Agent metaharness
One session, several agents, one set of rules
People and agents work one task on one context.
Live memory for the task at hand. Runs specialist agents from several harnesses in one session, routes context between them and enforces your policies.
 Enterprise context store
Permanent organizational knowledge, as a graph
Change the data model once, everything downstream follows.
Structured, versioned and accumulated over time on open source graph infrastructure. Everything downstream is derived from it.
What it connects to
Existing models and governance
What the organization already wrote down
Pulled into the store as the organization wrote them. Governance tools stay the master.
Modeling
Governance
 Collibra
 Alation
 Atlan
 Unity Catalog
 Horizon Catalog
Documentation
 Legacy ETL and dbt projects
Other IDEs and harnesses
The same context, in the tools your team already uses
Marketplace skills install in these harnesses too.
 Claude Code
 Codex
 Cursor and other IDEs
 Snowflake CoCo
 Databricks GenieAgents your team builds
Data platforms
Code, semantic views and metrics land where the data lives
Cloud
SnowflakeDatabricks Microsoft Fabric
 BigQuery
 Redshift
On premises
 Oracle
 SQL Server
 PostgreSQL
Code as
dbt models Spark SQL
Filled by
Read by
 Coding agents
A versioned graph
Every version of the data model is a version of the graph. A change is a proposal, whether an agent or a person made it, and the diff shows which entities, objects and products change. A locked version is what the generator builds from.
Served over MCP
The modeler builds the graph, and engineers query it from Claude Code, Cursor, Snowflake CoCo, Databricks Genie or any agent over MCP. Whoever asks reads the same governed graph and gets the same answer. Governance tools stay the master; the store reads from them and never writes back.
Works from the store
VaultSpeed agentsClaude CodeCodexCursorSnowflake CoCoDatabricks GenieYour own agents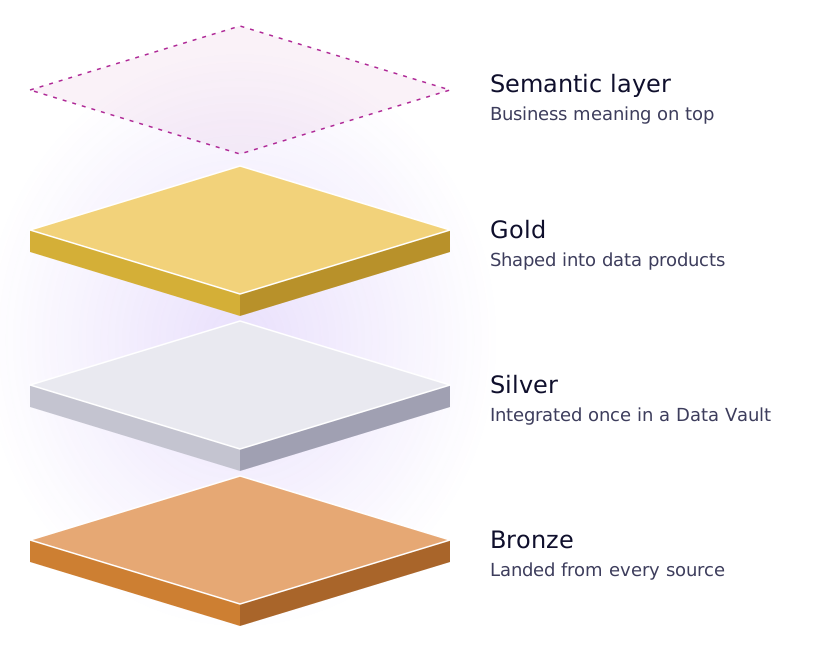
Language models
Your platform's LLMs, your token budget
Every agent reaches its LLM through the gateway. Point the gateway at the inference your organization already pays for and governs, and the tokens, the data boundary and the audit trail stay where your data platform already is.
Inference on Amazon Bedrock
Provisioned by VaultSpeed in your subscription's region and ready from the first session. The gateway points at it out of the box.
Claude with your own Anthropic key
Bring the API key your organization already holds with Anthropic. The gateway calls Claude on your contract, your rate limits and your usage dashboard.
Which LLM you use is a configuration, not an architecture decision. In every case the LLM works from metadata in the context store; your data stays where it lives. Details on how the platform is secured are on the trust center.
Customer story · Retail
Thanks to VaultSpeed, we industrialized our data layer without compromising agility or compliance. Our teams build and deploy data products faster, smarter, and at scale.
 Colruyt Group: warehouse rebuild and modernization at very high volume, data products on SnowflakeRead the story