Customer · Legal, tax and regulatory
Thomson Reuters runs a unified Data Vault layer on Snowflake to absorb continuous M&A
 M&A data integration and warehouse migration, 100+ business systems, data product marketplaceAll customer stories
100+ systems, many acquired
Data that was hard to find after years of acquisitions
Thomson Reuters runs more than 100 business systems, many of them brought in with acquired companies. For a long time the company worked as a holding company, and acquired businesses kept their own systems. About ten years ago that changed: acquisitions now move onto the core systems, but the older systems are still in use every day.
Each time a system or a team moved, some knowledge of the data and the processes behind it went with it. The team saw the cost when it built a customer activation data set for two business units. For the first unit, the data product went straight into the CRM. For the second, the same result took four to six weeks of extra work, part of it manual.
The program started from one question: why can’t the business find data it understands and can use? The data warehouse ran on an on-premises Oracle system, and the move to the cloud became the chance to rebuild the data foundation itself.
Proof in eight weeks
Three SAP tables combined in eight weeks, where two in-house attempts had not delivered
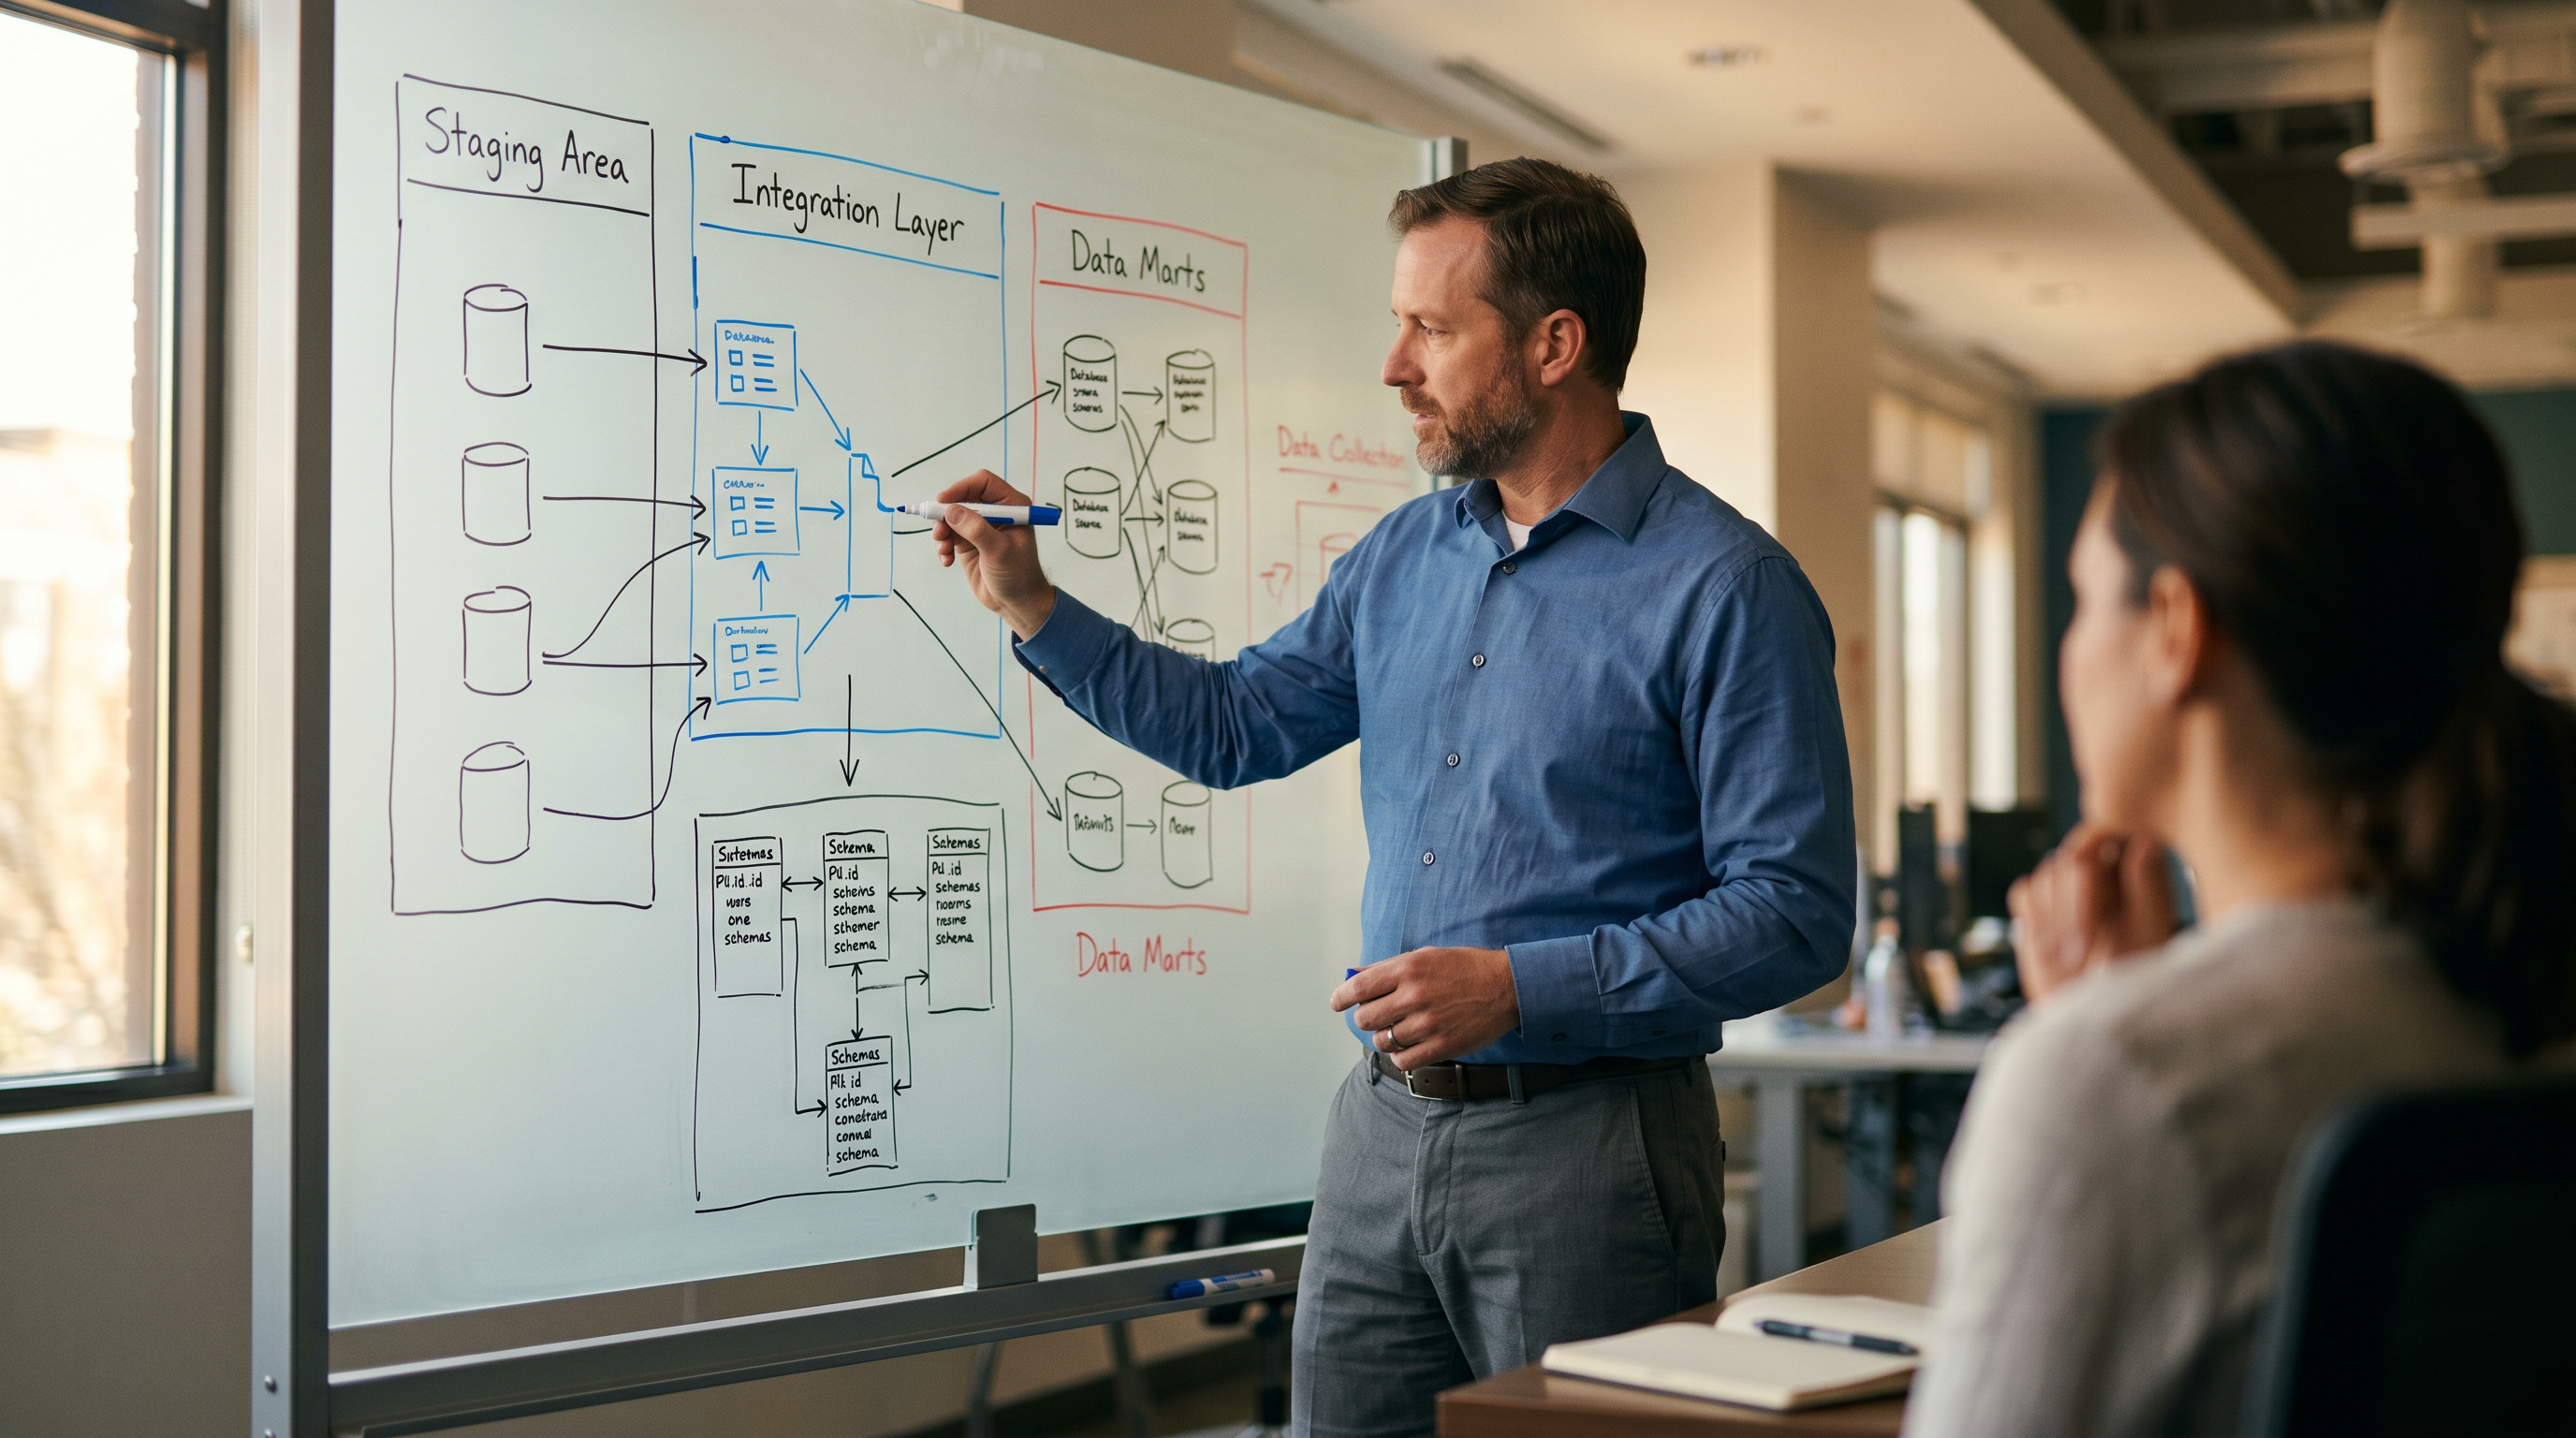
The team chose Data Vault because the business never stops changing: new acquisitions keep arriving, and every few years a large transformation reshapes the source systems. Two earlier attempts to build the Data Vault loading in house did not deliver what the team needed.
Deloitte introduced VaultSpeed. In the first piece of work, Deloitte combined three large SAP tables, one from S/4HANA and one from ECC, and showed the result in eight weeks, which neither earlier in-house attempt had achieved. That was late 2023, and it convinced the Chief Data Officer to adopt VaultSpeed.
“Once you lay the basic foundation, incremental changes are not as onerous as before.”
Anup Bommu, AVP Data & Analytics, Thomson Reuters
One domain at a time
Four data products first, then the SAP transformation
The data foundation is a lakehouse on Snowflake on AWS, with a unified Data Vault layer generated by VaultSpeed. Each business domain gets its own connected data products: Power BI dashboards, or tables and views people can take into Excel. A lightweight marketplace, tied to the data catalog, lists them so people can find them.
| Year | Milestone |
| 2024 | Four data products in the master data domain, starting with the customer and contact masters. The team learned Data Vault and VaultSpeed and set up the foundation on AWS and Snowflake. |
| 2025 | Complex data products, including the first data sets of the SAP move from ECC to a custom S/4HANA. In year one of a four to five year program, the data model and loading logic for the most important data sets were in place. |
| Now | Data products across domains; Finance alone has six or seven. The legacy warehouse is close to being switched off. |
Acquisitions follow a fixed first step. Whatever the company, its customer and product data are extracted from every system and loaded into the enterprise customer and product data, which feed the new warehouse. The CRM and billing systems are always migrated next; what follows depends on the company.
“Because of the confidence we gained with VaultSpeed, in 2025 we took on some complex data products and delivered them successfully.”
Anup Bommu
Moving off the old warehouse
Close to retiring a warehouse that ran 25 years
The legacy data warehouse had run for more than 25 years; apart from SAP, it was the oldest system still in use. After about three and a half years, the team is close to switching it off.
The old warehouse and the new lakehouse ran side by side so the main consumers had time to move. Teams had planned six months to a year of parallel running. Some moved in three months and others in one to six, once they saw the new data was better and more timely.
| Result | Detail |
| Legacy warehouse | Close to being switched off after about three and a half years |
| Consumer migration | Teams moved in one to six months, against six to twelve planned |
| Finance | Six or seven data products in one domain |
| Core team | Ten people: two data modelers, one architect and data engineers, with contractors for large source projects |
“I thought it was not a bad approach, to retire a warehouse that lasted 25 years in about three, maybe three and a half years, without any major fires.”
Anup Bommu
Data products for AI
Curated data products as the base for AI
Around 2023 and 2024, the common view inside the company was that a curated layer added little, because compute made it possible to combine any data on the fly. That changed once people saw that AI gives more accurate answers on curated data with a semantic model on top. The team is now asked for more data products with a semantic layer, so approved users can connect their AI assistants to them.
Access to the data also built trust: advanced users can open the underlying data and check a number with an AI assistant when something looks wrong, and their confidence in the new platform rose quickly.
The work continues on two fronts: the SAP transformation runs for several more years, and new acquisitions keep coming in.